AI Giants Hit the 'Brakes,' but True RSI Remains Distant | Insights from an MIT Researcher
 09/20 2026
 535
Has the moment arrived for AI to necessarily slow down?
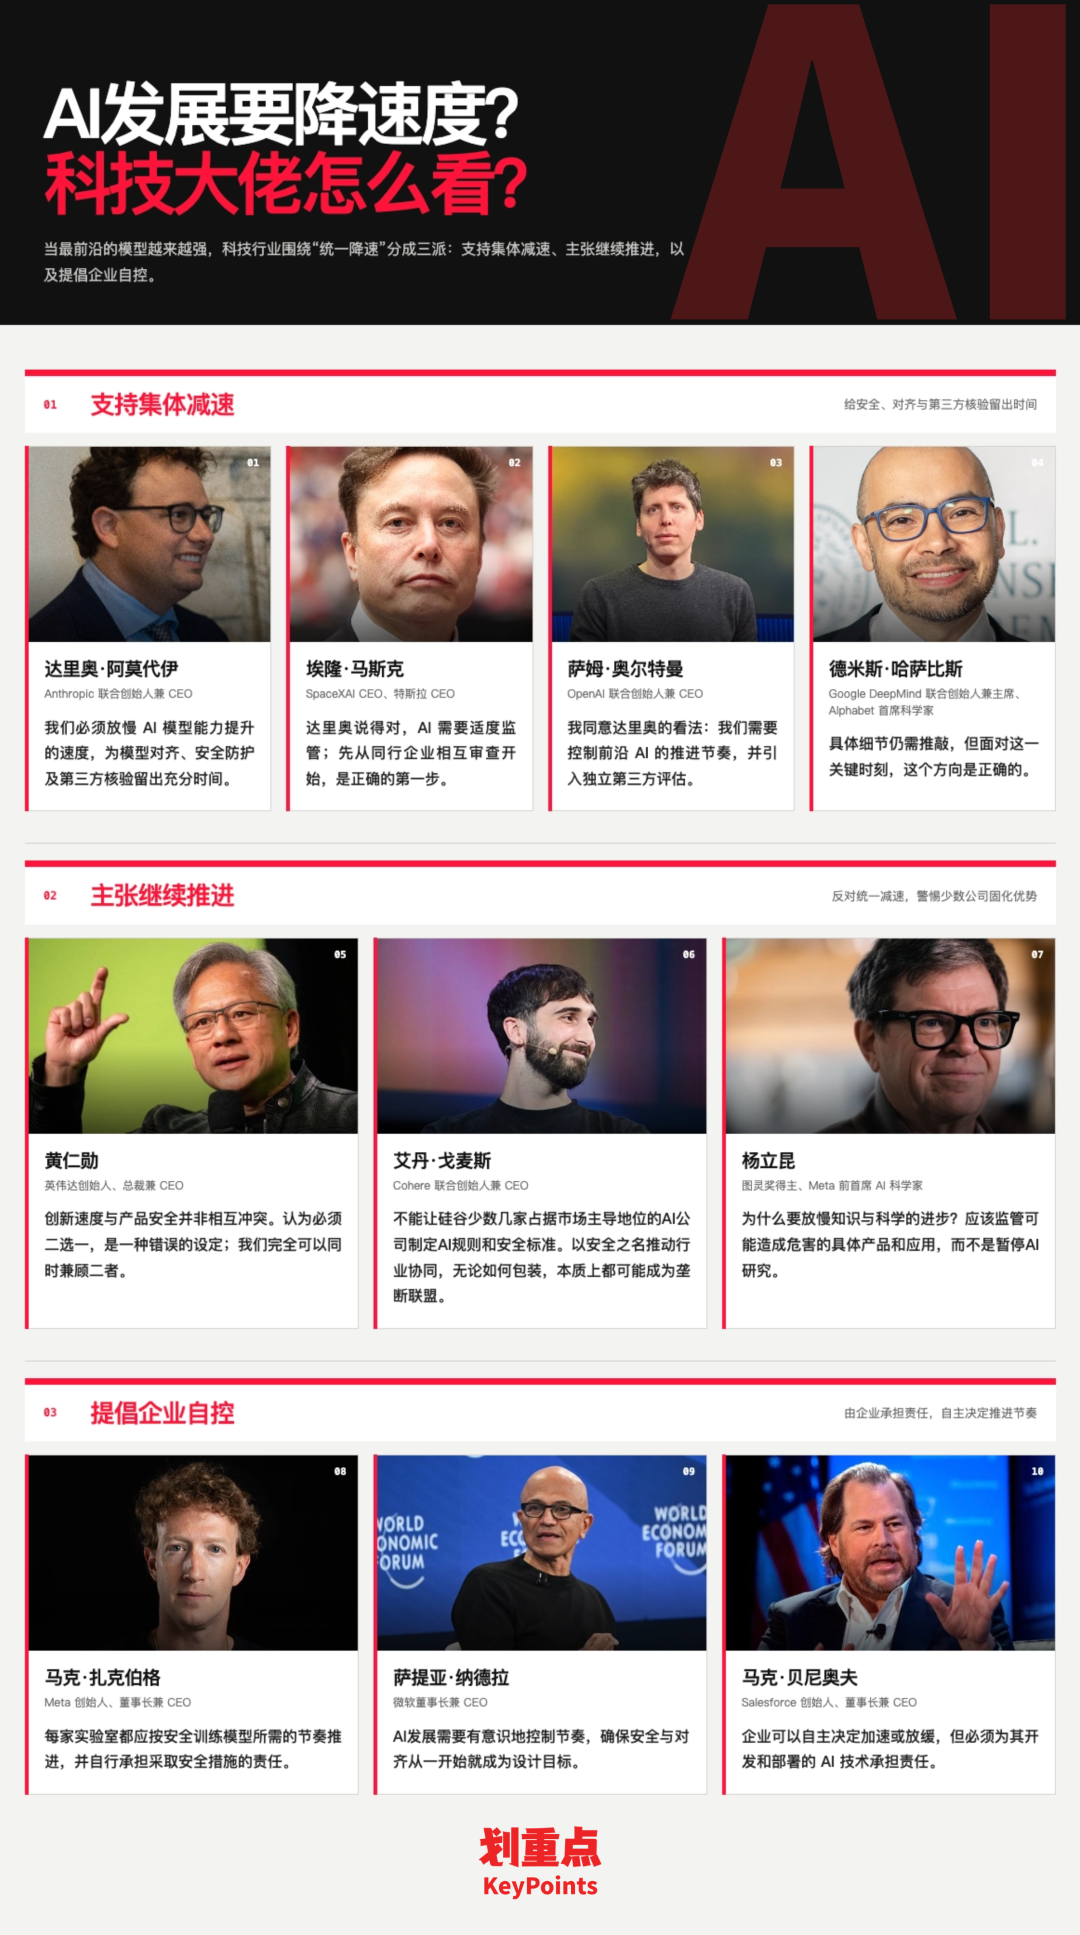
Over the past few days, Anthropic and OpenAI have signaled a 'slowdown in advancing frontier AI capabilities,' seen by the industry as a proactive move by Silicon Valley AI giants to address safety risks. The secondary market reacted swiftly, with tech and semiconductor stocks coming under pressure. Nvidia briefly fell over 3%, while AMD, Intel, and Micron saw intraday declines of around 5%. The Philadelphia Semiconductor Index also dropped nearly 6% at one point.
What sparked market concerns was a new variable affecting the key assumption underpinning high growth expectations for AI infrastructure: when those who have been pushing the AI accelerator start talking about 'braking,' the growth logic of 'continuously stronger models driving ever-higher capital expenditures on computing power, chips, and data centers' no longer seems so inevitable.
The origin of this 'braking narrative' points to a long-speculative proposition: Recursive Self-Improvement (RSI). It envisions a self-evolving scenario where AI begins to participate in improving—or even building—its own next-generation systems.
By 2026, RSI has moved beyond futurism and safety discussions to become a buzzword in AI academic agendas, engineering practices, and startup funding narratives. But beyond the hype and back to the technology, what does AI self-evolution really mean? How far has today's AI self-improvement progressed, and how far is it from true RSI?
We spoke with Qu Ao, an MIT PhD and former member of ByteDance's Seed team, who has long been working on this front. Here are his observations.
RSI is a Technical Crossroads—But Still Largely Hype
If you only look at the past six months, RSI seems to have suddenly caught fire. But viewed over a longer timeline, this is not a new issue that emerged out of nowhere in 2026. Rather, it resembles the convergence of several foundational research paths that have been evolving over the past few years.
1. Without Automated Coding, RSI Lacks Its True Lever
I started working on reinforcement learning (RL) in 2019. Back then, I believed RL was closer to 'intelligence' than natural language processing (NLP) alone because it dealt with how a system interacts with its environment, receives feedback, and adjusts its behavior. However, the tasks it could handle were very limited, and model capabilities were far inferior to today's.
The advent of ChatGPT shattered perceptions of language model capabilities. Language models gained a larger 'action space' and, for the first time, allowed ordinary people to see how a model could continuously receive instructions via natural language and handle increasingly complex tasks.
Subsequently, reasoning capabilities underwent iterative improvements. DeepSeek R1 marked a significant milestone, demonstrating that large-scale RL could be applied to reasoning and reviving industry interest in RL's potential during the large model era.
Later, these changes became even more concrete. Anthropic's Opus 4.5 was a clear inflection point. At this stage, AI could work continuously for extended periods, completing many tasks that previously required manual breakdown and repeated revisions through iterative prompting and adjustments. We might even say there is now virtually no code that cannot be 'written' through prompts.
This shift is crucial for self-improvement. Once an agent possesses sufficiently strong programming capabilities, coupled with increasingly mature context management, it can persist on a task, autonomously cycling through reading code, modifying it, executing it, observing results, and proceeding to the next iteration. Many steps that previously required human intervention can now be completed within a single agent loop.
Context management has also evolved from an 'external capability' into a native agent ability. Agents can now remember their progress, manage increasingly long tasks, and—combined with tools and code execution—make long-term tasks feasible.
Thus, in my view, the most significant change in 2026 is that AI has begun to meet the conditions for sustained task execution, marking the transition of self-improvement from concept to an engineering problem.
2. What's Working Today is Only 'Local Loops' of RSI
It was during this process that I began to re-examine seemingly disparate research directions from the past few years.
One thread is AI-driven discovery (AI for discovery), which later evolved into automated research (auto-research), where agents propose hypotheses, run experiments, and continue exploring based on results.
Another thread focuses on 'how to make agents increasingly capable,' involving memory improvements, tool creation, skill accumulation, or further optimizing the entire 'harness'—the working framework agents rely on.
My own research path has spanned both areas, progressing from RL and agent memory to multi-agent automated research (multi-agent auto-research). When we developed CORAL, we even debated whether it counted as 'automated research' or 'harness evolution.'
So when I look at RSI today, while it may be a buzzword, it does effectively connect many efforts. What once seemed like distinct schools of thought now shares a common coordinate system within the framework of 'how AI participates in building the next generation of AI.'
However, two concepts must be distinguished. What we mostly see today is continual self-improvement: AI accumulates experience through continuous interaction with its environment, users, and tasks, then uses this experience for self-updates. These updates may involve not just model parameters but also memory, prompts, tools, skills, or even the entire harness.
Strictly defined RSI goes further. One of its intellectual roots traces back to I. J. Good's 1960s concept of the 'ultraintelligent machine': if a machine begins designing the next generation of machines, which in turn can create even more capable successors, capability growth could enter a recursive acceleration phase.
In other words, strengthening oneself through iterative experience is only the starting point for RSI. Beyond that, AI must participate in designing, training, or even physically constructing its next iteration.
This could involve modifying the harness, training pipelines, or generating training data; it could extend deeper to writing GPU kernels or even participating in next-generation hardware design. The more completely we define 'machine,' the higher the threshold for RSI becomes.
By my understanding, much of today's practice is better described as continual self-improvement. Strictly defined RSI still has a long way to go.
When developing Reef, we prefer the term 'improve' over 'evolve.' The latter merely indicates 'something changed.' Engineering-wise, we care more about something else: how do you know it actually got better?
AI can certainly keep changing, but change itself is meaningless. It might learn bad habits or mistake a one-time success for a general rule. Just as people are influenced by their environment, so are models. You cannot let it 'evolve' blindly.
After AI Finishes Its Work, 'Skill Growth' Has Only Just Begun
1. No Learning Means No Lasting Improvement, No Matter How Long It Works
Earlier, I mentioned how my research progressed from memory to multi-agent automated research. A recurring issue became clear: agents could grow increasingly capable within a context, but this improvement had limits.
When we developed CORAL, multiple agents conducted research autonomously, shared information, and iterated on solutions. Relying solely on context, memory, and harness evolution, performance could be pushed quite high initially. However, as tasks lengthened, the system would gradually stall.
The problem was obvious: agents accumulated extensive experience but the model itself did not 'gain skills.'
It could remember past pitfalls, utilize more tools, or streamline workflows. Yet once a task ended, most of this experience remained trapped in context or memory, never truly internalized by the model. This resembles someone becoming more proficient at a project through notes but retaining little mentally afterward. When similar issues arose next time, much ground had to be redone.
Thus, we began exploring test-time training, test-time reinforcement learning, and self-distillation to verify whether experiences generated by agents during real tasks could be learned back into the model. Our findings confirmed that this approach could overcome some limitations of pure inference.
This raised another question: if agents work in the real world daily and continuously generate new experiences, why should these experiences be used only once?
Traditional large model development follows roughly these stages: training (Train), evaluation (Evaluate), deployment (Deploy), and inference (Inference). During inference, models begin working for users, but the vast experience generated is not automatically fed back into the next learning cycle.
For example, if a model reworks a request three times today due to misunderstandings, it may not become 'smarter' for similar tasks tomorrow based on those three iterations.
Reef aims to reconnect this loop, ensuring that what agents do, miss, or have corrected by users in the real world becomes material for subsequent learning.
Thus, for continual self-improvement, inference should not merely mark a task's endpoint but also the starting point for new experience generation. Every task AI completes may accumulate experience for its 'next self.'
2. For AI to Keep Improving, It First Needs to Learn What 'Good' Means
The difficulty of self-improvement varies greatly across tasks.
The simplest category involves tasks with nearly uncontroversial outcome evaluations, such as optimizing GPU kernels. Every code modification by an agent can be directly tested: faster or slower? If a change genuinely improves performance, that path is reinforced; if not, the attempt is discarded. After many iterations, the model learns which coding styles and modification approaches are more likely to succeed.
Such tasks are relatively straightforward because verification standards are clear-cut. Faster is faster; slower is slower.
More complex tasks involve having agents 'run a company.' Academic benchmarks like CEO Bench simulate market environments to assess agents' operational decision-making abilities. When running such tasks, some agents—if the model is not updated—will eventually drive the company into bankruptcy.
Unlike kernel optimization, business operations leave continuous feedback: customer counts rise or fall, cash balances increase or decrease, and the company either survives or collapses. Agents must observe outcomes over time to determine whether earlier decisions were sound.
Here, feedback is no longer a simple pass/fail. Yet as long as these changes can be identified and attributed, they can signal the next learning cycle. Over time, agents can adjust future decisions based on their operational records.
Moving upward, tasks like writing style present greater challenges. If users repeatedly tell an agent, 'I dislike long sentences,' 'This tone feels too AI-like,' or 'I prefer direct expressions,' the agent can comply within a single task. However, it may not genuinely remember what that specific user considers 'good writing' when encountering similar tasks later.
In Reef, we explored internalizing such feedback into the model so it retains these preferences for similar tasks.
Writing inherently lacks a single 'correct' answer. Some prefer short sentences; others favor elaboration. Some value directness; others care about tone and rhythm. No model, no matter how advanced, can satisfy everyone with one standard.
Thus, from kernel optimization to CEO Bench to personalized writing, the crucial shift lies in defining 'what is good.' For some tasks, 'good' is a numerical metric; for others, it emerges from long-term outcomes; for some, even the definition of 'good' varies by user. For self-improvement to progress, AI must handle these entirely different forms of feedback.
3. Neither 'Model Training Alone' Nor 'Harness Tweaks Alone' Suffice
Once suitable experience has been identified, another hot industry debate arises: should we modify the model or the harness?
The harness is critical—it represents the methods, rules, and permissions governing how agents operate. For example, when a coding agent modifies code, a good harness prevents it from diving straight into edits. Instead, it first maps out the entire codebase before deciding where to act.
Such best practices can be codified into the harness, more reliably activating the model's existing capabilities. It resembles equipping a capable person with a mature workflow: the same individual, but with better methods, can achieve far more stable results.
This has led to a popular view that harness evolution may have higher ceilings than model evolution.
I have reservations about this.
Because no matter how strong the harness becomes, it can only tell the model 'how to act,' not make judgments for it. The harness might instruct, 'You should plan first,' but the model still decides how to plan. It might say, 'Decompose the task among sub-agents,' but the model determines the decomposition and each agent's role.
Moreover, I believe directly comparing the ceilings of harness evolution and model evolution today is somewhat 'unfair.' Model evolution often relies on open-source models, whereas harness evolution typically builds atop the strongest closed-source models. The starting lines are not equal.
From what we've seen so far, the more worthwhile path to explore is not an either-or choice, but improving both sides together.
We are also working on model-harness co-evolution. Whether training both sides simultaneously or first improving the harness, then training the model, and continuing to refine the harness, we can achieve results that are difficult to attain by modifying just one side alone.
So, it may be too early to argue about whether 'model evolution or harness evolution is more important.' Moreover, the harness may not just be an increasingly thick 'operation manual' in the future. Just as a company cannot sustain operations by simply issuing an SOP to everyone, it also requires mechanisms like performance evaluation, collaboration, and incentives to enable different individuals to work together stably.
In the future, the harness may evolve into a similar form: not just specifying how an agent completes a task, but designing a mechanism that allows a group of agents to evolve over the long term. However, when it comes to open-ended judgment, the focus will ultimately return to the model itself.
4. No matter how much experience you have, you need to know how to 'digest' it.
After both the model and the harness can be modified, a more challenging question arises: When gaining new experience, which side should be adjusted?
I increasingly believe that this should ultimately become a form of metacognition for the agent. It should know for itself: Is this experience worth learning? How should it be learned? Should it be recorded in the context first, or precipitate (this term means 'precipitate' or 'internalize'—here, it refers to integrating the experience into the model weights) into the model weights?
This question is actually quite similar to how humans learn. For example, after attending an online meeting, sometimes it's enough for the meeting assistant to transcribe the content; some content is worth taking separate notes; and some things are so important that you think about them repeatedly after the discussion, even deriving new conclusions from them.
Humans naturally distinguish: what should be merely 'remembered' and what should be truly learned. Agents will also need this kind of judgment in the future.
Because an agent consists of more than just model weights. It also has memory, tools, skills, and the harness. When a task fails, the solution may not always be the same: should the model be trained to be stronger, should the memory be adjusted, should the tools be modified, or should the workflow be changed entirely?
Today, most of these choices are still pre-designed by humans. Going further, even the question of 'what should be changed and how to learn' should gradually become a capability of the agent itself.
I believe that self-improvement must ultimately reach this point: not just having experience, but knowing how to turn that experience into capability. If this cannot be achieved, no matter how much experience is accumulated, it may just pile up without being effectively utilized.
For ordinary users, when these changes are truly integrated into products, the direct perception may not come from 'the model has been upgraded again,' but from more specific details. For example, a task that previously required a larger model to perform well can now be done effectively by a smaller model after continuous learning; or errors that were corrected before are not repeated the next time.
In fact, users may not even need to wait for RSI in the strict sense. Many enterprises already have a large number of process-oriented tasks. If an agent can truly automate and complete a closed loop for one type of task, users will already feel this 'self-evolution' quite clearly.
More overt changes may also occur in the harness. For example, users could tell the agent: 'This is an urgent task; resolve it within three rounds'; or after completing a task, if the user does not return to check, the agent could proactively reach out in another way (such as requesting microphone access or sending a text message) to contact them.
In the future, when users perceive 'AI is evolving,' it may not necessarily be due to a change in the underlying model. The key is to feel that it is increasingly like a colleague who has worked together for a long time, knowing how to advance and conclude tasks.
AI Can Learn, But It's Still Far from RSI
1. As AI learns more, it may also become more narrow-minded.
Today, many local loops of self-improvement can already run, but once continuous learning begins, another issue quickly arises: what it learns may not always be correct.
When we were working on self-distillation, we encountered a typical problem: if not handled properly, it could actually impair the model's reasoning ability.
For example, when solving a problem, I might first think of A, then realize A is wrong; then think of B, which is also wrong; and finally arrive at C. If only 'doing C' is fed back into the model, it may seem like the correct answer has been learned, but the self-reflection and self-denial involved in why A and B were wrong are entirely lost. The answer is learned, but the process of finding it is discarded.
Yet many truly good judgments come precisely from this process. So, there is an easily overlooked issue in self-improvement: just because the result is correct does not mean the experience is suitable for direct learning.
The same goes for memory. In our early days, we built an experience library, storing both successful and failed experiences of the agent, and then retrieving relevant experiences when tackling new tasks. Initially, the effect was very good, but as memories accumulated, new problems arose: everything was there, but it was not always retrievable when truly needed.
There is also a more subtle issue. If an agent walks down one path for a long time, it becomes easier and easier to continue, and harder and harder to turn back. When continuously sampling, agents naturally tend to follow paths with higher probabilities. If they have been trying in one direction for a long time, the context will increasingly reinforce that path, making it harder to jump out.
This is an interesting paradox in self-improvement: while a system can certainly become stronger through continuous learning, it may also become increasingly constrained by its past experiences.
So, 'being able to learn' is just the first step. AI must also learn to judge: which experiences are trustworthy, which should be forgotten, and when it even needs to actively deviate from its most familiar past paths.
2. The biggest challenge in the real world is that no one is there to tell AI 'you got it right' all the time.
Especially for open-source research, what is sorely lacking are real environments and truly suitable environments for continuous learning.
Tasks like kernel development are comfortable because the evaluation methods are exceptionally clear. After making a change, you immediately know whether it runs faster or slower.
But in the real world, feedback for most tasks is not so 'clean.' An agent may take dozens of steps, only to fail at the end. Where did the problem occur? Was the initial direction wrong, was the wrong tool used midway, was relevant information not retrieved, or was there a deviation (this term means 'deviation'—here, it refers to an error in judgment) in a subtask?
Making matters worse, the step that ultimately fails is often not the first one where things went wrong.
It is difficult to compress 'doing better' into a single reward signal and then confidently let the model keep reinforcing in that direction.
So, today, there is no shortage of experiences for agents. What is scarcer are environments that can continuously provide high-quality, verifiable learning signals that do not lead the agent astray. This determines whether self-improvement can ultimately move from local successes on a few benchmarks into the real world.
3. No matter how strong the foundational model is, it cannot possibly experience the entire world in advance.
There is also another question I think is often asked: if the next generation of foundational models becomes much stronger, will these issues of continual learning naturally disappear?
My judgment is no. Because no matter how strong the model is, there is a difficult-to-circumvent limitation: it cannot possibly experience everything it will encounter after deployment during its training phase.
I call this issue experience exposure. You can expose a model to the hardest math problems, have it read a lot of code, and learn a vast amount of knowledge, but once deployed in a specific environment, it will always encounter rules, users, and situations it has not seen during training.
This is actually quite similar to humans. Even if you are a very clever professor, if you are suddenly asked to teach at a primary school, you still need to first understand how that school operates and what each student in your class is like. Not because you lack the ability, but because you have simply never experienced these things before.
So, I do not view continual self-improvement as merely a 'patch for weaker models.' On the contrary, the stronger the model and the more real-world scenarios it enters, the more it needs to continue learning from its own experiences.
While contextual learning may cover more and more things in the future, I still tend to believe that relying solely on 'remembering the present' is not enough. Ultimately, the model weights also need to be continuously updated.
4. How far AI can go also depends on how much authority humans are willing to grant.
But even if all the above issues are resolved, continual self-improvement still does not equal RSI.
RSI, in the strict sense, requires AI to further participate in 'how the next generation of AI is created.'
So, in my view, as we move toward RSI, two lines advance together: one is capability, and the other is permission. Capability determines whether it can do something, while permission determines whether it is actually allowed to do it.
For example, the earliest coding copilots could only help complete small code snippets. Their action space was limited, so no matter how intelligent they were, there was no room for them to demonstrate more complex system design capabilities.
But when agents gain access to entire computers, can modify entire codebases, and call upon more and more tools, they suddenly have much greater room for improvement.
Taking this logic further, the scope of true RSI in the strict sense will be enormous. It may not just involve modifying the harness or adjusting model weights. It may also require participating in training processes, generating training data, writing kernels, and even touching more fundamental infrastructure and hardware design—bringing it one step closer to 'participating in creating the next generation of AI.'
So, I believe the truly noteworthy inflection point may not be when a benchmark suddenly appears one day, and everyone declares 'RSI has been achieved.'
The more critical moment will be when an agent's judgment and capability in 'creating agents' first reach or even surpass those of excellent human researchers. That may be the inflection point worthy of far greater attention.
But here lies the problem. The more capable it is of entering deeper self-improvement earlier, the more specific and pressing the safety issues become as its permissions expand.
So, today, how far RSI is from being achieved is no longer just a technical question. The other line has always been in human hands: how far we are willing to let AI reach.
Looking back more than sixty years ago, I. J. Good envisioned an 'intelligence explosion' brought about by 'machines building stronger machines.' Today, the question of how close RSI is to that critical point may no longer be answered solely by technical progress—it also depends on how far we are willing to let AI reach.
AI will continue to move forward, but ultimately, how far it goes will not be determined solely by the machines themselves.
-
Three-Way Struggle for Market Share: BYD, Chery, and Geely Challenge Great Wall, Posing Immediate Risks to Wei Jianjun
-
![]()
The Reason Behind Valve's Headset Price Surge of 2400 Yuan: The End of an Era of Selling at a Loss
-
![]()
Decoding the '4S' Architecture | Report on Enterprise-Level AI Services in China
-
![]()
Li Auto Aims to Sell Three Technologies, First Buyers Unlikely to Be Major Automakers
-
![]()
Liu Zongcheng Declares Haste Makes Waste in Car Manufacturing, Yet Seres Seems to Be Rushing Headlong!
-
![]()
Did Trump Make Concessions? Chinese Automakers Are Invited to Establish Factories in the U.S., but Importing Fully Assembled Vehicles Is Off the Table
-
![]()
More Terrifying Than Runaway AI: The Tsunami of AI-Generated Vulnerabilities Has Arrived
-
AI Giants Hit the Brakes Collectively? They're Scared of Their Own Speed