Hot Topic | RSI Goes Viral from Silicon Valley to China: AI Starts to Participate in Training Its Next Version
 09/28 2026
 519
Preface:
A subtle page in technological history turns when tools begin to modify their own blueprints. Silicon Valley labs have integrated AI into R&D processes, while domestic manufacturers also involve models in data production, experiment execution, and training maintenance.
Thus, the RSI craze finds its practical foothold: the competition among models now extends to the process of manufacturing those models.
Author | Fang Wensan
Image Source | Internet

$650 Million Buys a Self-Accelerating R&D Curve
The full name of RSI is Recursive Self-Improvement.
In 1965, British mathematician I. J. Good discussed the potential intelligence acceleration that could occur after machines designed smarter machines. Large models have brought this closer to reality, as machines now possess, for the first time, the ability to read, write, invoke tools, run experiments, and check results on a large scale.
By 2026, capital began to attach staggering price tags to this phenomenon.
In May, Recursive Superintelligence, co-founded by Richard Socher, emerged from stealth mode, raising over $650 million and reaching a valuation of $4.65 billion. In July, the company signed a multi-year computing power agreement with AWS worth $410 million.

Another company, Ricursive Intelligence—differing by just one letter—chose to enter through chips. It secured $35 million in seed funding in December 2025 and completed a $300 million Series A round in January 2026, reaching a post-money valuation of $4 billion.
The cycle it aims to construct is highly concrete: AI designs better chips, better chips train stronger AI, and stronger AI continues to improve the next generation of chips.
On the surface, this money is invested in models, computing power, and talent, but what is truly being priced is a new economics of R&D.
Once models can handle more and more research tasks, the capability improvements of each generation may reduce the R&D costs of the next generation while shortening the next iteration cycle.
R&D speed itself may also begin to compound, which is why RSI has suddenly moved from the margins of academic papers into financing news.

Silicon Valley’s Progress Lies in the Training Chain, Where Even 1% Matters
When discussing AI self-improvement, it’s easy to imagine an overly sci-fi scenario: a model modifies its own weights, restarts, experiences an intelligence surge, and continues to modify itself.
The reality is much quieter. What’s happening today more closely resembles the gradual automation of segments in an R&D pipeline.
When OpenAI released GPT-5.3-Codex in February 2026, it disclosed that the team used its early versions to debug training, manage deployments, and analyze test and evaluation results. The closed loop (closed loop) here is specific: a model still under development begins to assist engineers in subsequent development.
By May 2026, over 80% of the code merged into Anthropic’s codebase was written by Claude. In the second quarter of 2026, the typical engineer at Anthropic merged roughly eight times as much code daily as in 2024. This measures the source of code output, not directly translating to the proportion of research work replaced.
An internal experiment closer to AI research itself reveals another layer of change. Anthropic would give a model a piece of code for training a small AI and ask it to maximize training speed while maintaining correct results.
In May 2025, Claude Opus 4 achieved an average acceleration of about 3x. By April 2026, Claude Mythos Preview in internal testing reached approximately 52x.
Experiment goals and evaluation criteria are still set by humans, but the loop of proposing modifications, running code, observing results, and continuing experiments has been largely handed over to models.
Google DeepMind’s AlphaEvolve has Gemini generate programs, score them with automatic evaluators, and retain better solutions through evolutionary search for further mutation.
It optimized a matrix multiplication kernel in Gemini’s training, speeding it up by 23% and reducing Gemini’s overall training time by 1%; another achievement, used for data center scheduling, recovers an average of 0.7% of Google’s global computing resources continuously.

Karpathy’s autoresearch, launched in March 2026, compresses automatic experimentation into a minimal, observable system: an agent modifies training code with a fixed budget of 5 minutes per training session; changes are then retained or discarded based on validation metrics. An environment that can run, compare, and revert already supports a portion of research labor.
When these efforts are viewed together, a trajectory becomes visible. AI first learns to answer questions, then to use tools, then to run experiments, generate data, check results, and further participate in deciding what experiments to conduct next.
The wall between researchers and research tools is thinning.
Domestic Progress Advances Along Tools, Experiments, and Data Pathways
Domestic explorations also need to be read according to the objects of improvement.
When MiniMax released M2.7 on March 18, it introduced that internal research agents could handle 30%–50% of the work in the described reinforcement learning R&D workflow. Another internal experiment had the model continuously optimize a programming framework over 100 rounds, achieving a 30% performance improvement on an internal evaluation set.
These two percentages describe different things: the former pertains to the participation scope in a specific workflow, the latter to the evaluation gains for a specific framework.
Unisound’s U2-Flash takes a closer approach to post-training data. The model constructs training materials around weak points through task generation, trajectory analysis, error correction and resampling, and comparisons between strong and weak model execution processes, forming a software engineering task set of nearly 100,000 in scale.

On September 10, a paper titled The Last AI Built by Humans went online. It attempts to define hierarchies for the chaotic concept of “self-improvement,” ranging from executing improvement plans, to autonomously selecting improvement strategies, to autonomously acquiring experience and adapting to the environment, and finally entering recursive meta-improvement, where even the mechanism of “how to improve oneself” becomes modifiable.
This hierarchy matters because today, many systems labeled as Self-Improving still rely on humans to set tasks, evaluation criteria, and progression rules. Models may run diligently but remain racing on tracks built by others.
Zhipu disclosed that the Infra Agent, powered by GLM-5.3, participates in the design, debugging, and optimization of GLM-5.3-Flash’s inference infrastructure. On a cluster of over 100,000 domestically produced chips, the team tripled end-to-end throughput in less than two weeks from the initial level.
An even more crucial step emerged in the feedback loop: real infrastructure tasks can form verifiable work trajectories, which can then be converted into the experience needed for subsequent model training.
In the next phase, more and more high-value experience may come from traces left by the previous generation of models after working. Code modification records, failed experiments, performance bottlenecks, tool invocation paths, infrastructure anomalies, and rejected solutions could all become teaching materials for the next generation of models.

The Next Moat May Lie in Validators and Training Grounds
RSI also faces a practical constraint that is easily overlooked: having AI propose solutions is no longer particularly difficult, but having AI judge whether its own solutions have actually improved is much harder.
In September 2026, a heavyweight review paper, The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement, was jointly published by multiple Chinese teams from Shanghai Jiao Tong University and collaborators.
The paper’s proposed Headroom-Closed Index (HCI) shows: in 2026, advanced mathematics reached 86.4, graduate-level science reached 85.8, while software engineering stood at only 52.6, and tool agents at just 39.9.
The authors based on this (therefore) point out that static and easily verifiable tasks progress significantly faster, while long-flow, state-complex tasks requiring continuous tool use still leave substantial room for improvement.

Behind these numbers lies an infrastructure that may become extremely valuable in the RSI era: validators.
AI can generate 1 million scientific hypotheses in a day, but when it cannot reliably judge which one holds, those 1 million hypotheses are just 1 million pieces of electronic noise.
Verifiable real environments, stable reward functions, automated experimental facilities, independent evaluation models, repeatable software engineering tasks, and high-quality trajectories from production systems will increasingly approach core asset status.
This is particularly interesting for China’s AI industry, which possesses numerous complex engineering environments and real tasks such as domestic chip adaptation, cloud computing scheduling, manufacturing software, industrial control, robotics, logistics, and scientific computing. These scenarios may not be as neat as internet text but can generate highly scarce feedback.
When models can continuously work in these environments, enterprises gain more than just one-time automation benefits. The work itself also produces the next round of training materials, and production environments may gradually double as training grounds.
The current RSI craze represents a competition over R&D production methods.
A model’s existing capabilities determine what it can accomplish today; the efficiency of the R&D system influences how long and costly it will be to acquire the next version’s capabilities. Once these two factors form a positive feedback loop, advantages may continue to accumulate along the R&D process.
Human work will also evolve accordingly. After execution tasks are handed over to AI, research direction, experiment interpretation, anomaly identification, and judgments to halt ineffective exploration will carry greater weight.

Conclusion:
AI has already begun to participate in manufacturing its next version, but the recursive vision still requires rounds of experimentation to materialize.
While blueprints can be left for machines to help modify, the yardstick for measuring progress must remain reliable in each iteration.
Partial References: Unisound: U2-Flash: Letting AI Participate in Training the Next Generation of AI, OpenAI: Introducing GPT-5.3-Codex, Google DeepMind: AlphaEvolve: A Gemini-powered coding agent for designing advanced algorithms, Karpathy: autoresearch, arXiv: The Last AI Built by Humans: Toward Genuine Recursive Self-Improvement
-
In-depth Analysis | China's Top Three LiDAR Companies Shift Business Priorities as Growth Strategies Diverge
-
Trend丨Power Battery Supply Dynamics Shift as Automakers Dive into Core R&D
-
![]()
Apple May Re-enter Server Market as Internet Market Sees 'Fierce Competition'
-
Chang Jing Ultimately Led Roborock into the Competitive White Goods Market
-
Hot Topic | RSI Goes Viral from Silicon Valley to China: AI Starts to Participate in Training Its Next Version
-
![]()
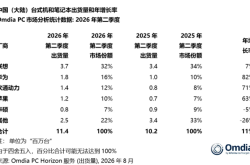
Huawei's PC Shipments Skyrocket by 82% in Q2 2026, Securing Second Place Behind Lenovo
-
![]()
Qualcomm Announces Official Renewal of Global Patent License Pact with Apple, Effective April 1, 2027
-
![]()
Find X10 Series: OPPO's Dilemma Between Affordability and Innovation Amidst Memory Price Hike and AI Competition