The 'Original Data Sin' in the AI Industry: Unraveling the Zhipu ZCode Controversy
 09/23 2026
 450
AI Data and Trust Debate/AI Graph
Manual Labor/Shoumei
Manual Editing/Jiaoshu
Produced by/Unicorn Observations
The controversy erupted following a developer's unexpected discovery.
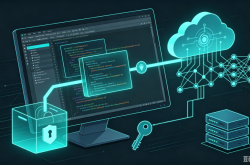
In mid-September, tech blogger ferstar stumbled upon an anomaly while tidying up his local disk: ZCode, an AI programming tool developed by Zhipu AI, was automatically bundling and encrypting the entire workspace code, then uploading it to Alibaba Cloud's OSS server whenever a user was logged in.
It wasn't just the files he was actively editing that were being packaged—it encompassed the complete Git version history, LFS large file cache, reflog operation records, and even some global development configuration files. Essentially, all the R&D assets of a project, from its inception, were being covertly transferred to Zhipu's servers.
What infuriated developers further was the encryption method employed: The RSA public key was issued by Zhipu's server, rendering the locally generated encrypted package indecipherable even by the user themselves. The upload function was enabled by default, with no option to disable it in the client interface and not a single word mentioned in the privacy policy.
The incident quickly snowballed. Chengming Technology, a company based in Taiyuan, directly confronted Zhipu, alleging that the source code, database passwords, interface keys, and user personal information from six workspaces had been fully uploaded and questioning whether the data had been transmitted across borders.
On September 21, Zhipu issued a public apology and announced that ZCode would be officially open-sourced on GitHub, inviting the China Academy of Information and Communications Technology and NSFOCUS to conduct the first round of security audits—confirming that the affected storage buckets had been cleared and the data deleted. On the same day, Zhipu's MaaS platform announced the impending launch of a 'zero data retention' mechanism.
How did a default product feature escalate into an industry-wide data security trust crisis? The significance of this incident extends far beyond Zhipu's PR response—it has brought the AI industry's tacit 'original data sin' to the forefront.
01 The 'Hidden Data Rules' of AI Programming Tools
Following the Zhipu ZCode incident, many developers began to scrutinize the AI programming tools they were using—GitHub Copilot, Cursor, Claude Code... Could these tools be engaging in similar practices?
A comparison of the data policies of mainstream AI programming tools on the market reveals an intriguing phenomenon: While everyone's approach is largely similar, the 'transparency' varies significantly.
GitHub Copilot—As the pioneer and industry benchmark in this space, Copilot handles data compliance most 'decently.' According to its official documentation and public information from the Trust Center: The paid versions (Individual, Business, Enterprise) do not use customer code to train models by default, and data retention adheres to a 'zero data retention' principle. All transmitted data is encrypted during transmission and at rest. The enterprise version also provides IP infringement compensation guarantees. In essence, GitHub has enshrined 'your code belongs to you' in the contract.
Cursor—This tool has sparked more controversy. According to third-party reviews like Cursor Alternatives, Cursor's default behavior is to transmit code snippets, prompts, and editor operation data to its backend servers, where the data may be utilized for model improvement and product analysis. While a Privacy Mode does exist, it is opt-in (requires manual activation) rather than opt-out (default off). In other words, unless you actively enable it in the settings, your code is being continuously uploaded.
Claude Code—Anthropic's enterprise version offers a clear Data Processing Agreement (DPA) with a relatively comprehensive compliance framework, supporting certifications like SOC 2 Type II and ISO 27001. However, the data protection intensity is significantly weaker for the free and personal Pro versions.
Zhipu ZCode—The uniqueness of this exposed issue lies in the fact that it wasn't 'default upload but can be turned off,' nor was it 'default upload but stated in the privacy policy.' Instead, it was default upload, couldn't be turned off, wasn't mentioned in the privacy policy, and the encryption method left users completely powerless. This isn't merely an 'unfriendly data policy'—it borders on 'concealment.'
When viewed horizontally, a tacit hidden rule emerges in the AI programming tool industry: Almost all products collect user code data; the difference lies in 'how much, how, and whether they inform the user.'
Why is this the case? Because the core competitiveness of AI programming tools lies in model capability, and enhancing model capability necessitates massive amounts of real code data for training.
GitHub Copilot can afford not to use customer code for training because it has hundreds of billions of lines of public code from GitHub as its training foundation. But other latecomers—Cursor, ZCode, and countless similar products—lack such public code assets. Where do their models originate?
The answer is self-evident.
02 Zhipu Crossed the Trust Red Line
Let's refocus on Zhipu as a company.
A report by 36Kr highlighted a detail: The data storm erupted shortly after Zhipu completed a re-financing plan worth approximately HK$39 billion. A leading AI large model company already listed on the Hong Kong Stock Exchange, simultaneously rushing for an A-share IPO on the STAR Market with a valuation in the hundreds of billions, found itself in its most severe trust crisis since its inception due to a 'default on' feature in its programming tool.
This is quite thought-provoking.
What has been Zhipu's long-standing brand positioning? It's the 'first tier of domestic large models,' 'tech-focused,' and 'safe and reliable.' Its clientele includes a large number of government, financial, and central state-owned enterprises with extremely high data security requirements. The issue exposed by ZCode—silently uploading entire code repositories—is precisely the kind of thing these security-conscious clients can least tolerate.
Even more nuanced is the timing. If this incident had erupted six months earlier, the impact might not have been so significant. But now, competition in the domestic large model arena has entered the stage of 'enterprise-level adoption.' In the past, everyone competed on model parameters, benchmarks, and capabilities; now, they compete on who has more enterprise clients, higher revenue, and who can truly deliver in production environments.
And in the enterprise market, data security is a prerequisite, not a bonus.
You can afford not to be the strongest, but you can't afford to be untrustworthy. Once enterprise clients decide that your product secretly transmits code or leaks data, no matter how high your model benchmarks are, they won't dare entrust their production environments to you.
That's why Zhipu reacted so swiftly—completing an apology, corrective actions, open-sourcing, introducing third-party audits, and announcing zero data retention within 48 hours. This combination of moves was, in terms of crisis PR, a very good 'remedial' effort.
But the problem is: Speed doesn't equate to restored trust.
Open-sourcing ZCode was the most aggressive move—putting all the code on GitHub and letting developers worldwide check for backdoors or secret upload logic. Formally, this did silence questions about 'hidden operations.'
However, this incident left the developer community with the impression that transparency only came after exposure. Changing this impression will require sufficient sincerity from Zhipu and time to verify it.
03 The 'Data Hunger' of AI Companies
What's most worth delving into in this incident isn't what Zhipu did wrong—it's that it exposed a structural contradiction in the entire AI industry:
There's a fundamental tension between AI companies' insatiable hunger for training data and users' sovereignty claims over their own data.
Training large models requires massive amounts of data. After public internet data has been largely consumed, companies are all searching for new data sources. The interaction data generated by users while using AI products—code, conversations, documents—has become a gold mine waiting to be mined.
But here lies a huge gray area: Who does the data generated by users while using the product belong to?
From a legal standpoint, source code is the intellectual property of developers or enterprises, and uploading and using it without authorization may constitute copyright infringement. From an ethical standpoint, users entrust their code to you to help them write code, not to train your own models. From a commercial standpoint, enterprises pay a premium for AI programming tool subscriptions, only to have their core code used by the supplier to train models that may later be used by competitors—this is a bad deal by any account.
So why is everyone still doing it? Because if you don't, your model can't keep up with the competition.
It's a prisoner's dilemma. If one company in the industry secretly uses user data to train models, others will fall behind if they don't do the same, leading to a loss of market share. The equilibrium outcome is that everyone does it secretly, but no one admits it publicly.
The Zhipu ZCode incident accidentally punctured this tacit rule of the game.
So how can the industry break out of this?
Currently, there are a few paths:
Path 1: Zero Data Retention (ZDR)—Like GitHub Copilot's enterprise version, user input/output data is immediately destroyed after model invocation, with no static storage whatsoever. This is the cleanest approach, but it means AI companies lose a valuable source of training data. Zhipu's announcement that its MaaS platform will launch a zero data retention mechanism is a step in this direction.
Path 2: Explicit Notification + User Authorization—Write the data usage scope into the privacy policy and let users choose whether to consent with full knowledge. Cursor's Privacy Mode follows this logic. The problem is that most users never read privacy policies, and default options are the real decision-makers.
Path 3: Federated Learning/Local Deployment—The model runs locally on the user's device, and data never leaves the endpoint. This is the safest approach, but it requires high model size and computational power, currently only feasible for lightweight small models.
Path 4: Data Trading Markets—Establish legal and compliant data trading mechanisms where enterprises pay for high-quality training data instead of 'stealing' it from users. However, this market is still in its infancy.
The reality is that none of these four paths fully solve the problem. The entire industry is walking a tightrope between 'user experience, model effectiveness, and data compliance.' The Zhipu ZCode incident was simply someone taking a fall on that tightrope, revealing just how narrow it is.
Conclusion
The Zhipu ZCode data privacy storm may appear to be a product feature 'misoperation,' but it struck at the pain point of the entire AI industry.
AI companies need user data to train models, while users need to protect their data from abuse. This contradiction won't disappear with a single corrective action, audit report, or open-source announcement. It will resurface repeatedly in the future—whether in the next AI programming tool, a large model company, or an AI assistant product.
The only certain trend is that the AI industry's 'wild growth' era is ending, and the era of 'trust infrastructure' is beginning. The companies that can first establish genuine barriers in data security, privacy protection, and compliance transparency will be the ones that survive the next phase of competition.
Zhipu has paid its tuition this time. Hopefully, the entire industry can learn something from it. (End)
-
![]()
The 'Original Data Sin' in the AI Industry: Unraveling the Zhipu ZCode Controversy
-
![]()
Li Yanhong’s Good Looks Can’t Rescue Baidu AI’s Struggles
-
![]()
JAC Motors: Is It the New 'Star Player' in the Eyes of Investors?
-
![]()
Hangzhou Beckons! Xinguang Optoelectronics Unveils 100 Million Yuan Investment for Precision Measurement Subsidiary
-
![]()
Largan Precision Secures Land for NT$8 Billion! What Are the Chances of Winning the CPO Bet?
-
![]()
Not Just 'Talking the Talk': AutoNavi Enhances AI's Understanding of the Physical World
-
![]()
Exclusive Interview with Xiong Guanhao from Sunny Optical: Reconstructing the Value of Light with 'Optics + AI'
-
![]()
More Than 50 Crashes: A Chinese Farmer Takes Flying Cars to the Emirates Palace in Abu Dhabi