Qwen, Tencent Hunyuan, and Kimi Tie for First Place in the Latest Chinese Large Model Rankings
 11/19 2026
 566
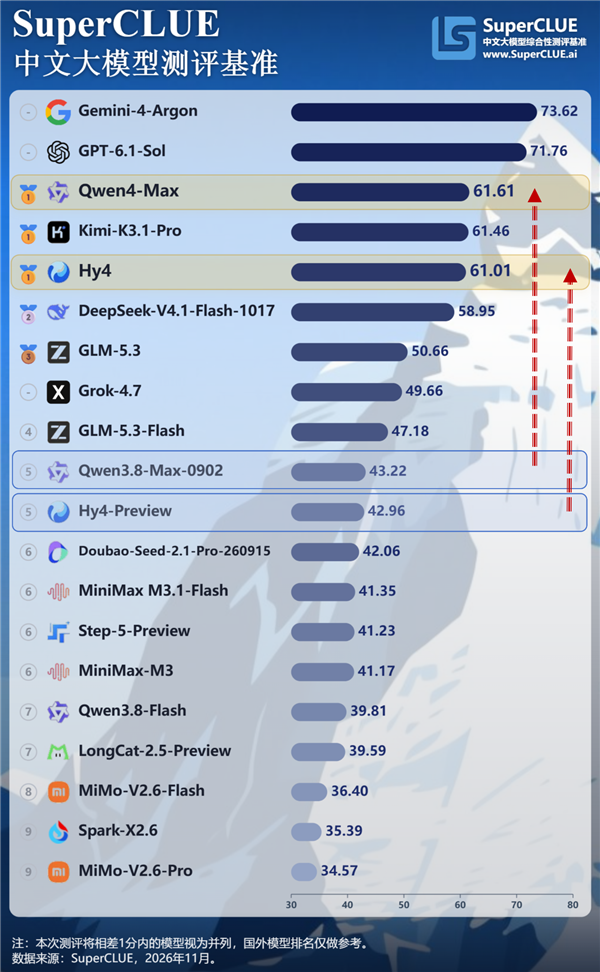
Fast Technology News, November 18: SuperCLUE has released the results of a new round of evaluations for Chinese general-purpose AI capabilities. Alibaba's Qwen4-Max scored 61.61 and Tencent Hunyuan Hy4 scored 61.01, both tying with KimiK3.1Pro at 61.46 for the top spot among domestic models.
Under the evaluation rules, models within 1 point of each other are considered tied. Compared with their previous versions, Qwen4-Max and Hy4 improved by 18.39 and 18.05 points respectively, both entering the top domestic tier.
Both models were officially released in November 2026. Qwen4-Max focuses on enhancing complex reasoning and engineering development capabilities while optimizing inference overhead; Hy4 adds native visual understanding and computer operation capabilities, strengthening long-text processing, agent planning, and code development.
In this evaluation, changes in coding ability and usage cost were especially notable. In the agent coding project, both models scored 57.69, up 15.38 points from their respective previous versions.
Previously, Qwen3.8-Max-0902 had a test timeout rate of 69.23%, and Hy4-Preview had 26.92%. This time, both new models completed all test questions without any timeouts, with timeout rates dropping to 0%, and the average number of output tokens per question also decreased significantly.
Based on the token usage and model pricing in this test, Qwen4-Max costs about 1.90 yuan per question on average, down about 87.0% from the previous version; Hy4 costs about 2.52 yuan, down about 28.5% from the Preview version. Task completion capability improved while per-question cost also came down.
In terms of sub-scores, Qwen stands out more in hallucination control. Qwen4-Max scored 73.61, up 40.56 points from the previous version, ranking first on the domestic sub-ranking; its ultra-long context score was 77.80, up 33.42 points.
Hy4 performed better in handling ultra-long content and accurately executing requirements. Its ultra-long context score reached 88.86, up 40.99 points from the Preview version; it scored 50.00 in precise instruction following, up 18.97 points, ranking first domestically in both categories.
From these results, the two models both raised overall scores and improved timeout and cost issues in coding tasks. Qwen leads in hallucination control, while Tencent Hunyuan took first place domestically in both ultra-long context and precise instruction following.
-
![]()
Why Did LG Sell 2 Million Clothes Care Machines in 15 Years? Where Do Chinese Brands Fall Short?
-
![]()
Lenovo Outpaces Apple in Both Shipments and Revenue: Lenovo's PCs and Tablets Gain Ground Through AI—What Lies Ahead?
-
![]()
At the APEC Meeting in Shenzhen, Wang Chuanfu, Lei Jun, Zeng Yuqun, and Li Yanhong Discuss the Future of Automotive Mobility
-
![]()
Tencent Sues PowerChina Huadong: 73 Court Hearings in a Single Year—Why Is the 45.4 Billion Yuan General Contracting Champion Sitting in the Defendant's Seat?
-
Gathering in Shenzhen: What Chinese Solutions Do Entrepreneurs Bring to the APEC Business Summit?
-
![]()
Chicago School District Takes on Google: Bundled AI Is Worse Than No AI at All
-
The Data Annotation Business Behind AI Music
-
![]()
Qwen, Tencent Hunyuan, and Kimi Tie for First Place in the Latest Chinese Large Model Rankings