DeepSeek Unveils Compact V4.1 Flash Model: SSD Cache Demand Slashed to One-Eighth of Its Predecessor
 10/19 2026
 342
Farsight, October 17th – DeepSeek has introduced its V4.1 Flash model, which boasts built-in visual comprehension capabilities and has concurrently rolled out its API. According to DeepSeek, the new model has significantly reduced its reliance on High Bandwidth Memory (HBM) and SSD storage compared to its predecessor. Specifically, HBM requirements have been trimmed to one-fourth, while SSD needs have been cut down to one-eighth, largely thanks to the optimization of the KV Cache.
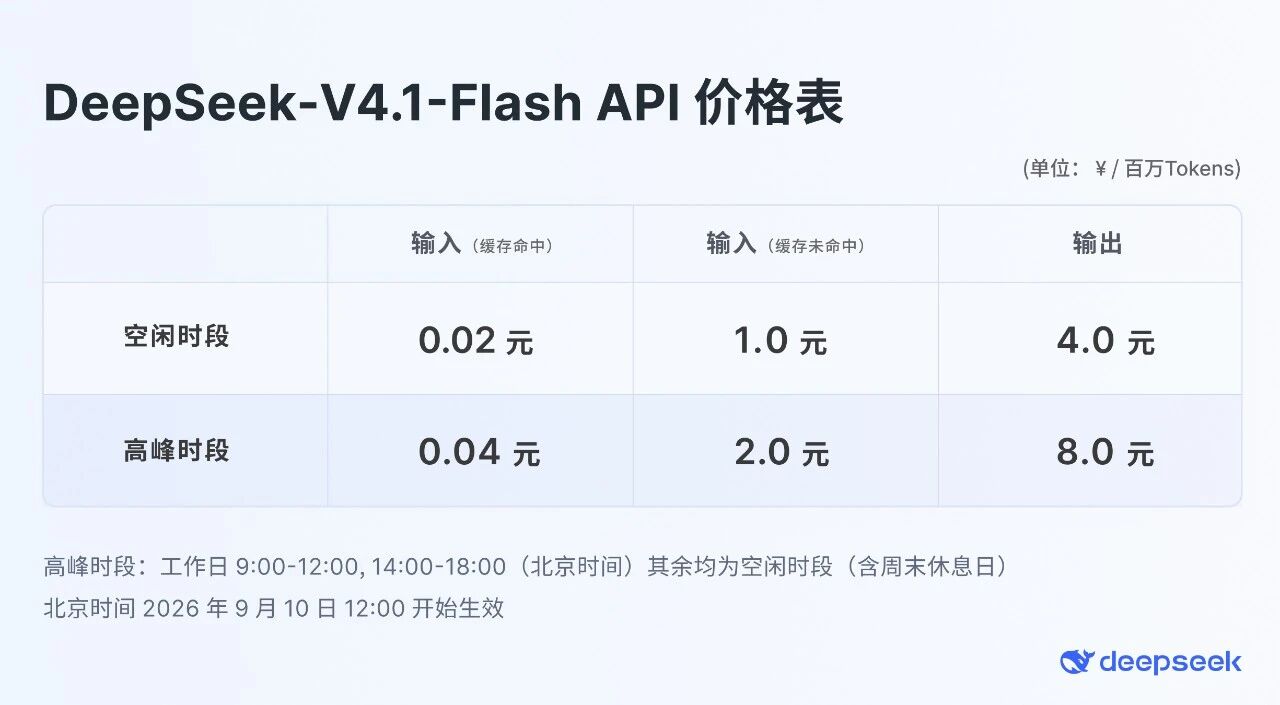
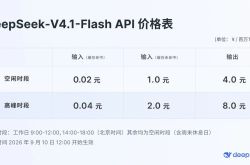
Regarding pricing, the V4.1 Flash API charges are based on per million tokens. During peak hours, the costs for input cache hits, input cache misses, and output are 0.04 yuan, 2 yuan, and 8 yuan, respectively. During off-peak hours, these charges are halved to 0.02 yuan, 1 yuan, and 4 yuan. Peak hours are defined as weekdays from 9:00 AM to 12:00 PM and 2:00 PM to 6:00 PM Beijing Time, with all other times, including weekends, considered off-peak. The aforementioned pricing structure took effect from 12:00 PM on September 10, 2026.
The V4.1 Flash model employs a Mixture of Experts (MoE) architecture, featuring a backbone parameter scale of 552 billion. During the input prefilling phase, 8 billion parameters are activated, while the output decoding stage sees the activation of 16 billion parameters. DeepSeek positions this model as the most compact offering within its new model architecture lineup.
Official details reveal that the V4.1 Flash model utilizes a structure comprising a causal encoder and decoder, which minimizes context storage overhead by refining cache generation and reuse strategies. The persistent KV cache occupancy is roughly one-eighth of that of the DeepSeek V4 Flash model; the global KV cache is condensed to approximately 890 bytes per token, which is about one-fourth of the previous generation's size. The former pertains to SSD storage, while the latter relates to HBM requirements.
This modification is primarily targeted at Agent tasks that necessitate handling substantial input volumes. DeepSeek notes that in Agent scenarios, cache hit costs often constitute a significant portion of the overall expenses, and compressing the cache aids in reducing usage costs. The official model page indicates that the V4.1 Flash model supports a maximum context length of 1 million tokens, accepts both image and text inputs, and generates text outputs.
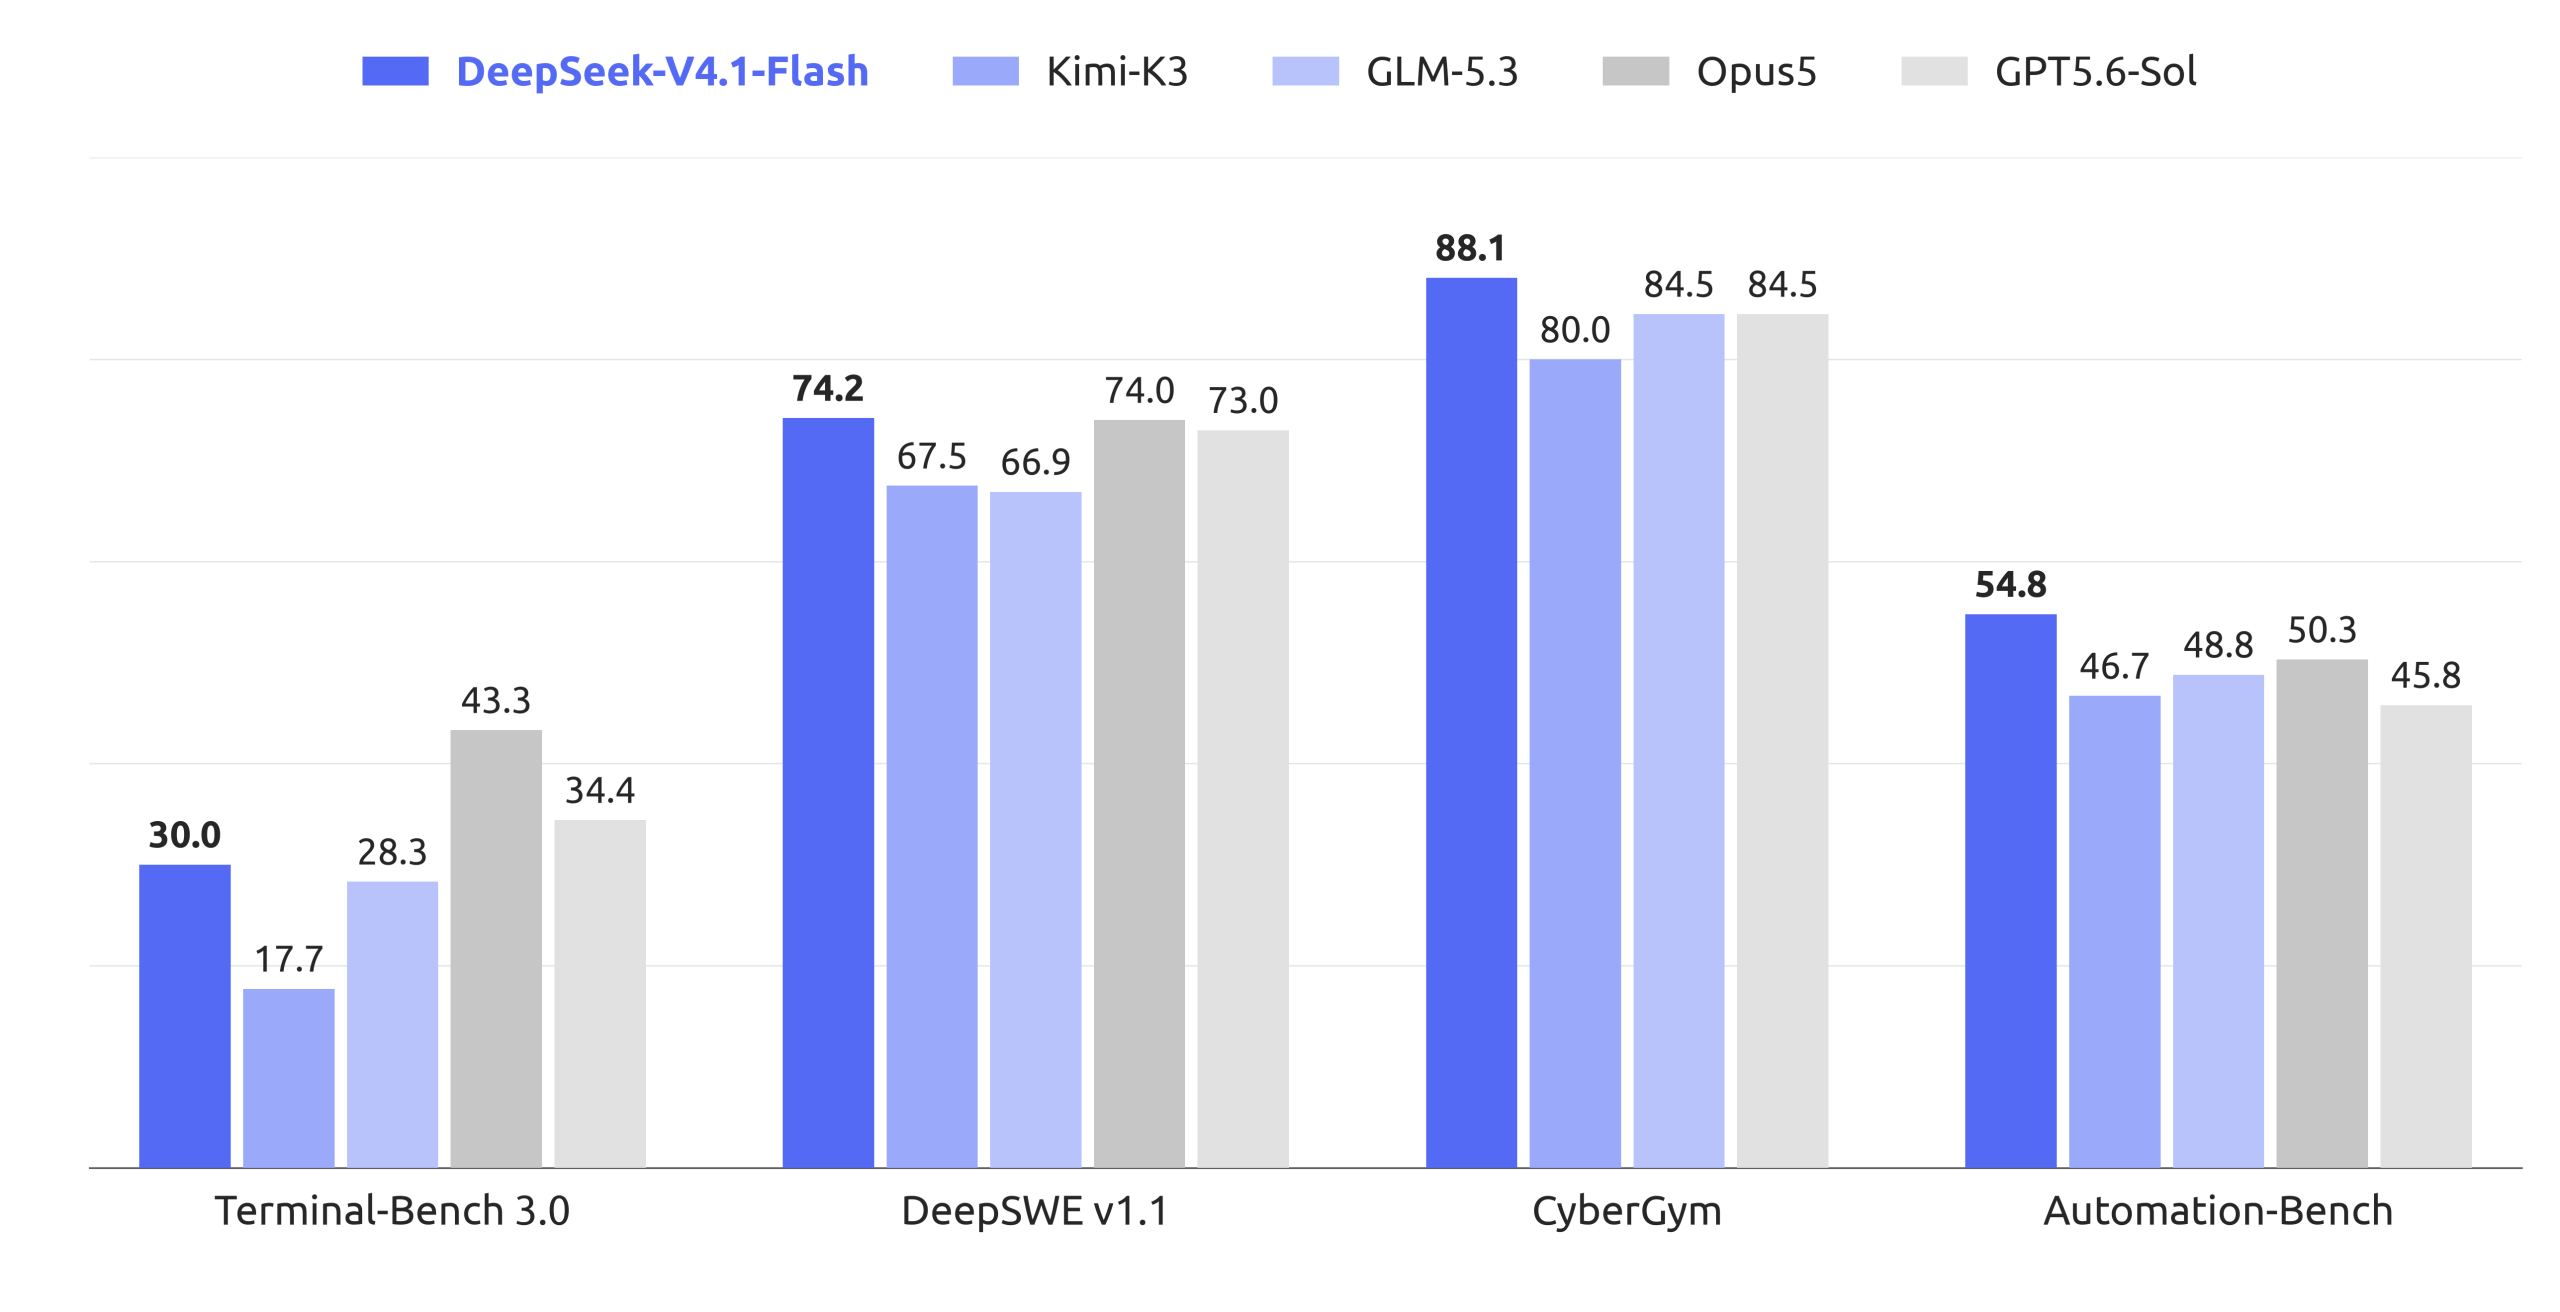
In terms of performance, DeepSeek asserts that following new pre-training methodologies and more extensive reinforcement learning post-training, the new model surpasses several flagship models, including the V4 Pro, in benchmark evaluations.
-
![]()
Why Are There No Issues During End-to-End Model Training, Yet Problems Arise in Real-World Deployment?
-
![]()
Why Does XPENG Need to Re-adapt VLA2.0 to European Roads When It Has Already Trained in China?
-
Report | China Academy of Industrial Internet: Industrial Agent Development Report
-
Trend丨OpenAI Teams Up with Synopsys to Launch GPT-Synopsys, Ushering in the Era of 'AI Autonomous Engineers' in Chip Design
-
![]()
Be Wary! AI Doesn't Just Fabricate Videos—It Can Alter Human Memories
-
Memory Costs Soar: Transsion, the Low-End Phone Specialist, Seeks Upgrade and Diversifies Business
-
Dongfeng Nissan Has Not Overcome Its 'Sylphy Dependence'
-
![]()
DeepSeek Unveils Compact V4.1 Flash Model: SSD Cache Demand Slashed to One-Eighth of Its Predecessor